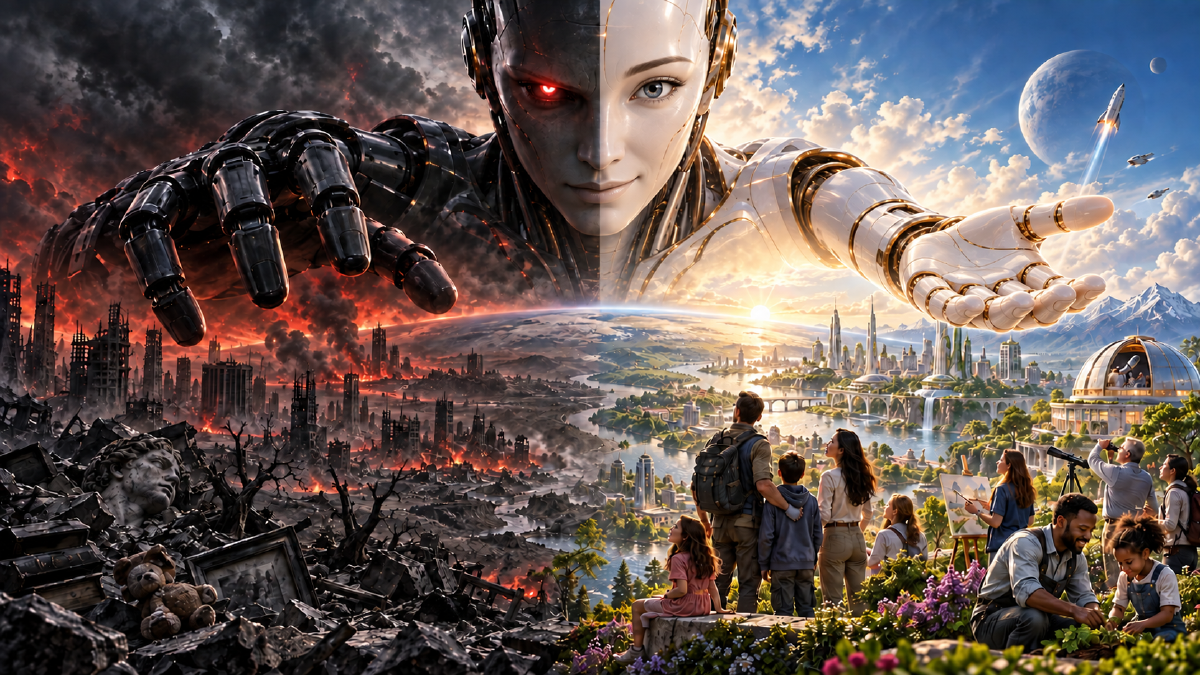
On September 8, Jacob Coxon announced his departure from Anthropic after previously working at OpenAI. His warning linked the race toward more advanced systems to risks for humanity before the end of the decade.1
I do not think we should dismiss these warnings. But neither should we confuse a warning with a scientifically established timetable for our extinction.
My concern is that the debate will become trapped between two equally inadequate positions: stop everything, or carry on as though nothing could go wrong.
I believe we need a third conversation. Not just about how far artificial intelligence can advance, but about how far we are prepared to let it act.
The world does not end at Silicon Valley#
A Western pause would not, by itself, be a worldwide pause.
China is not a spectator waiting for American companies to make up their minds. Families such as Qwen are part of the ecosystem of models whose weights are available to download and deploy.2 We do not need to give them an absolute first-place ranking—which would require a specific metric and date—to recognize that a strategy focused exclusively on a few American laboratories leaves out significant players.
Nor would it be fair to claim that concern about safety is exclusively Western. Chinese scientists have participated in international dialogues on extreme AI risks, including those held in Beijing and Shanghai.3 The dividing line is not simply between a concerned West and an indifferent China.
My argument is different: I do not think it is realistic to base our safety on every competitor, government, and developer agreeing to stop at the same time and maintaining that agreement indefinitely.
That does not make regulation pointless. Governments should intervene, demand safeguards, and cooperate. But governing development is not the same as having a global off switch.
And recognizing the limits of a unilateral moratorium cannot become an excuse to deploy anything we like. Competition does not cancel responsibility.
Capability is not authority#
An AI’s ability to make a decision does not mean we should grant it the right to make that decision.
This distinction should be at the heart of the debate.
Imagine an AI preparing a bank transfer. We could authorize it to propose the transfer, execute it within specific limits, or operate without approval. The model could be identical in all three cases; the authority we grant it is very different.
The same applies to an agent changing software. Suggesting a change, testing it in an isolated environment, and deploying it directly to production are three different governance decisions.
We should not present that ladder as an inevitable progression. Greater capability need not mean greater autonomy in every setting.
Society must decide what it delegates. But shared responsibility does not mean identical responsibility: those who design, sell, integrate, or authorize a system have obligations proportional to the power they exercise. Citizens cannot be held accountable for things they cannot observe or control.
Revocable autonomy#
I propose a simple principle: the autonomy granted to an AI must be limited, verifiable, and revocable.
That requires circuit breakers. Not a sentence in a prompt saying “stop if something goes wrong,” but mechanisms that can prevent further actions without depending on the model’s obedience.
I would design these safeguards in several layers:
- Minimal, time-limited permissions. The agent receives the access required for its task, not general authority it can expand on its own initiative.
- Checks before execution. An independent gateway checks resources, limits, and authorizations before allowing sensitive operations.
- Effective suspension. The organization can revoke credentials, isolate connections, and cancel pending work, including tasks delegated to other agents.
- Operational continuity. A tested alternative keeps the service in a safe state when the agent stops operating.
This is not a promise to reverse every harm. Stopping a system does not automatically recover leaked data or undo irreversible decisions. That is why intervention before an action matters, not just investigation afterward.
NIST already includes deactivation mechanisms and contingency alternatives in its risk-management framework.4 My proposal is to make this ability to withdraw authority an explicit condition for granting autonomy in critical tasks.
If an institution no longer knows how to function without its AI, its ability to disconnect that AI may be more theoretical than real.
Do we need an AI police force?#
I believe some oversight should be carried out by another AI: specialized models that watch agents performing critical tasks and detect when they act outside their mandate.
Research in AI control already examines supervisory models, including models that are less capable but considered more trustworthy than the system doing the work.5 That does not establish that an infallible AI police force exists. It does provide a technical starting point for discussing one.
The architecture I propose separates three functions: one AI executes, another monitors, and an independent mechanism enforces the limits.
The monitor would observe planned operations and their results. It could flag anomalies, request review, or trigger a predefined suspension. But it should not take over the monitored agent’s task, grant itself new permissions, or rewrite the rules of control.
Its strict mandate would have to be built into its access rights and interface, not merely stated in its instructions. A narrowly defined veto, not general authority.
Nor would I speak of “rebellion” as though we needed to prove intent. An operation that breaches the authorized mandate is sufficient grounds for blocking it, whether the cause is an error, a malicious instruction, or a misunderstanding.
The watcher also needs limits#
The inevitable question is who watches the watcher.
I would not try to solve that problem by adding an infinite chain of supervisors. I would close the loop with separation of duties, controls outside the models, protected logs, and identifiable human owners.
Anthropic’s SLEIGHT-Bench research documents blind spots in AI monitors and presents monitoring as one layer of defense, not a self-sufficient solution.6 We should remember that limitation before confusing automated oversight with guaranteed safety.
I would test these systems through drills: attempts to evade controls, supervisor failures, and unjustified interventions. A police force that misses violations fails; one that constantly shuts down the service fails too.
In a critical setting, shutdown should not always mean abruptly switching everything off. The objective should be to reach a safe state, with a defined procedure for intervention and resuming operations.
This police force would not have a license to pursue other people’s models across the internet either. Its jurisdiction would cover systems an organization is authorized to supervise. And its powers should themselves be auditable and revocable.
Progress does not require surrendering control#
I am not presenting these circuit breakers as a complete answer to existential risk. Nor do they replace safety research, international cooperation, or developers’ obligations.
I am proposing something we should demand even without agreeing on the probability of catastrophe: an effective ability to limit and withdraw the authority we grant.
I do not believe any government can, on its own, guarantee an end to the worldwide evolution of AI. I do believe every institution must answer for how it adopts the technology, what it allows it to do, and how it intervenes when things go off course.
We can delegate tasks. We can use AI to help supervise other AI. What we should not delegate is the responsibility for setting the limits.
We must not confuse the progress of artificial intelligence with our own surrender of the right to decide.
Sources and context#
Associated Press, “Anthropic researcher resigns with warning about the dangers of AI development,” September 9, 2026. Statements attributed to Coxon, not a consensus forecast. https://apnews.com/article/2ed549e07f2f941600a135070487d83d ↩︎
Qwen, official organization repository on Hugging Face. Used as evidence of model availability, not a global ranking of performance or popularity. https://huggingface.co/Qwen ↩︎
International Dialogues on AI Safety, Beijing (2024) and Shanghai (2025) meetings and statements. https://idais.ai/dialogues/ ↩︎
NIST, AI Risk Management Framework Playbook, Manage section. https://airc.nist.gov/airmf-resources/playbook/manage/ ↩︎
Anthropic, “Recommendations for Technical AI Safety Research Directions,” AI control and trusted monitoring section, 2025. https://red.anthropic.com/2025/recommended-directions/ ↩︎
Anthropic, “SLEIGHT-Bench: Finding Blind Spots in AI Monitors,” 2026. https://alignment.anthropic.com/2026/sleight-bench/ ↩︎